I need to get data from MAX6675 Cold-Junction-Compensated K-Thermocouple to-Digital Converter (0°C to +1024°C).
I need only to read 16 bit and I good. Sounds easy? Not so fast!
Almost every MAX6675 library used full-duplex SPI mode with sending dummy bytes to /null.
I don’t need that, I thought. Let’s configure Cube:
- Mode: Receive Only Master
- Data Size: 16 bits

Great, now a bit code:
Let’s add read function, HAL_SPI_Receive(pointer_to_spi, pointer to buffer, how_many_packets, timeout)
We need to receive only one 16 bit packet, so 1. Very good!
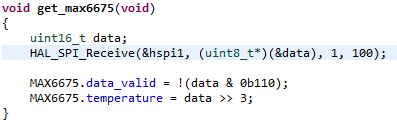
Let’s call this in interrupt (I need defined and time-controlled read time)
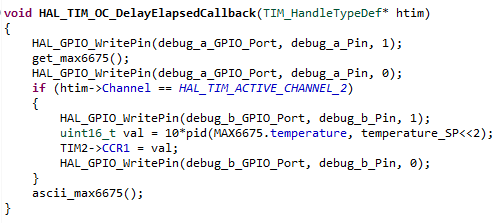
Wonderful! Let’s add output to debug_pin a&b to measure how long it takes to receive & process(PID) data.
But then I noticed something really strange.
First HAL_SPI_Receive call (after MCU reset), Receiving Data (pin debug_a) needs, as expected, ~ 16 bits, but, but… Why it samples 16 extra bits???
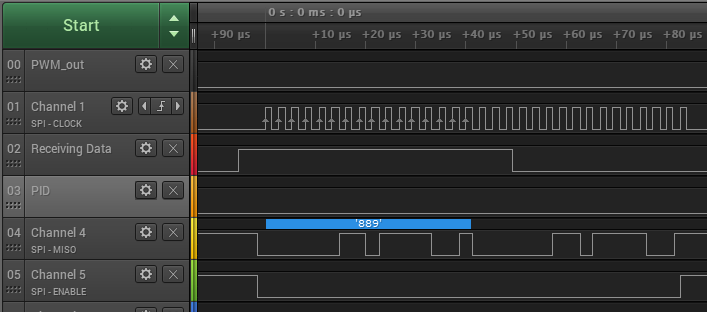
Each next HAL_SPI_Receive call returns data almost immidiately, and also samples 16 bits. WHY? WHAT? I need to receive only 1 package! I requested only 1 package!
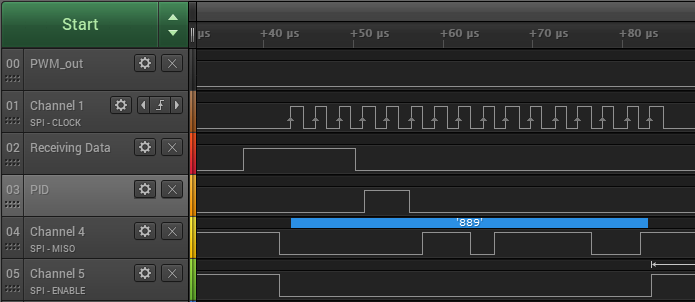
Ok, time for RTFM.
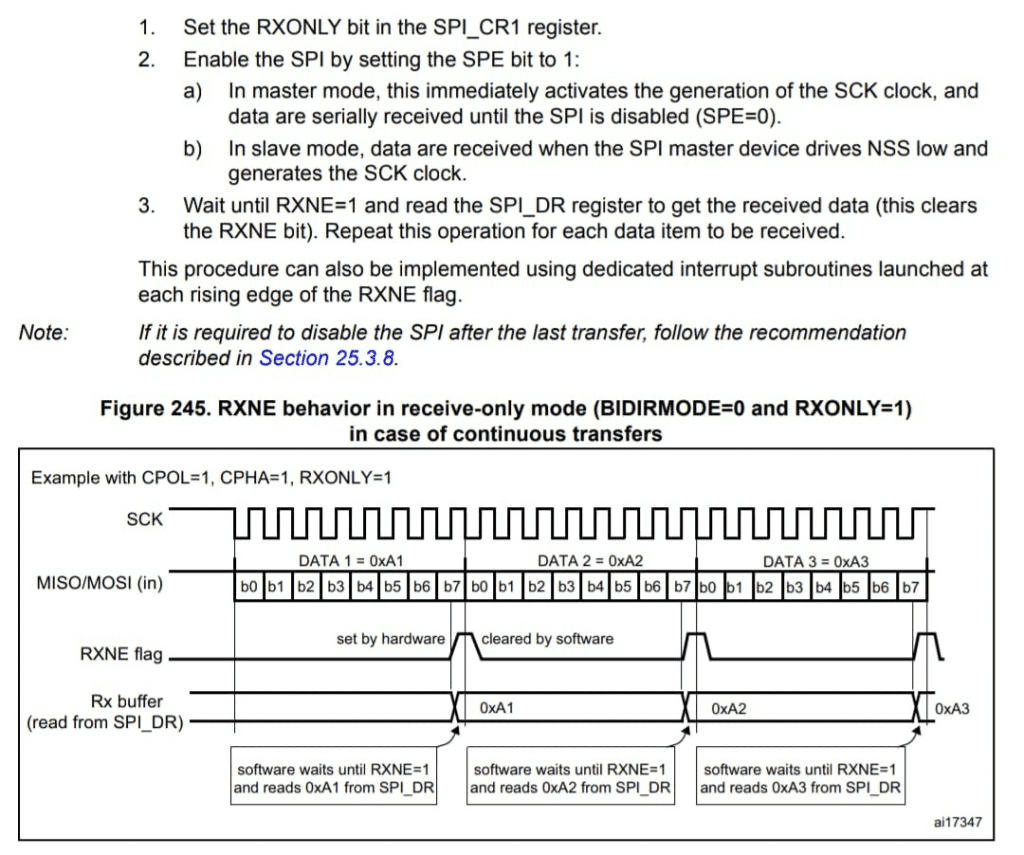
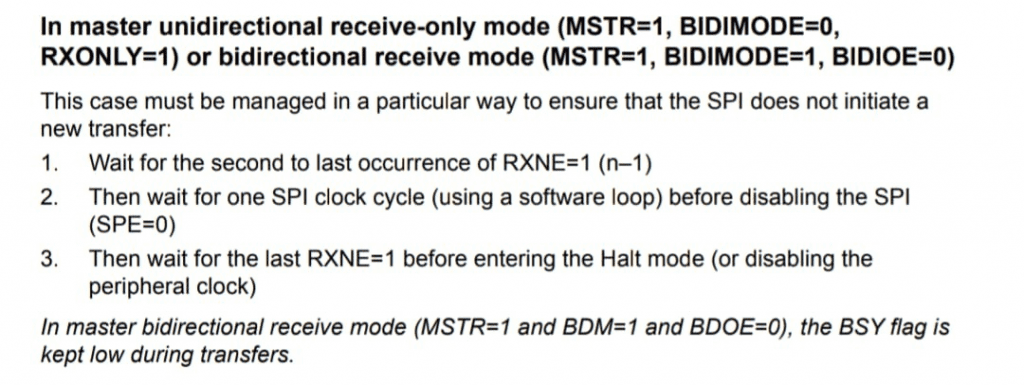
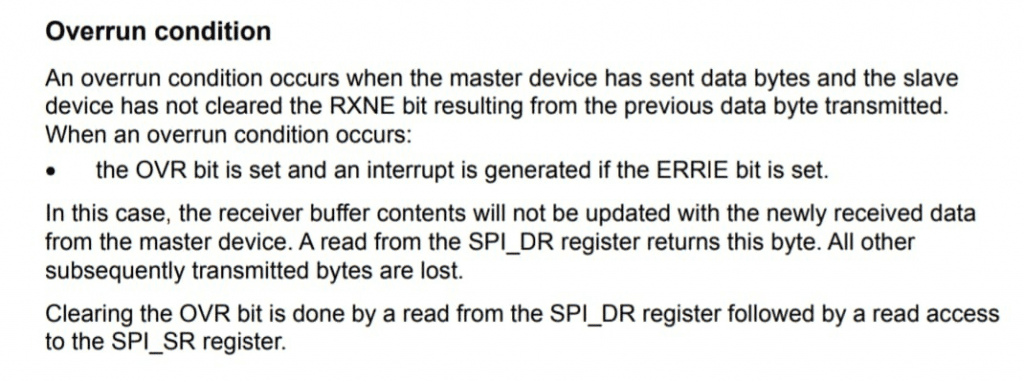
Uh, okay, yes, it makes sense! SPI is pretty easy protocol, you send bytes, you receive bytes. If you push out 1 bit, it clocks in 1 bit. So, if you send 2 dummy bytes, it’ll receive 2 real bytes. But if you want only receive, it virtually doesn’t know how many bytes you want to receive. So, it generates clock, and fills spi_data_receive regiter. And then waits place for the next packet.
With first packet comes first fresh data. And immidiately samples once again.
Each next packet – it takes from spi register data received last time, and immidiately uses it in software. SPI in backend at this moment finishes 16 bit sampling, and stores data for next time.
Quick fix – and now it looks as expected! (Note SPI SW Enabled debug output – as in manual, enable, receive one bit, and disable it)
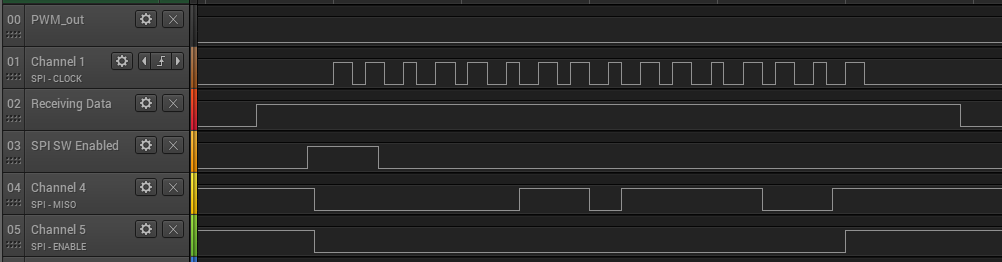
And so it looks in code only (added if RXONLY)
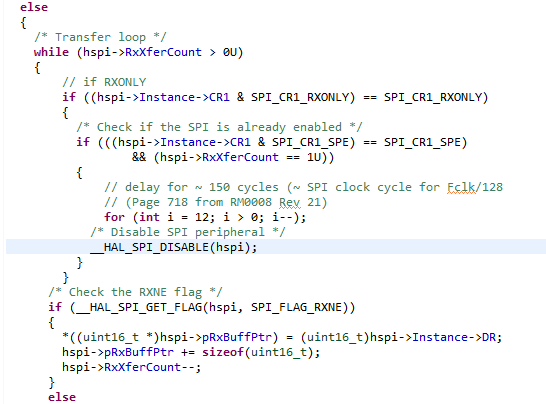
Unfortunatelly, this delay is dependent from SPI clock, and should be tuned for each frequency. Each for takes about 12 cycles, so for 128 cycles delay (for Fsck/128 SPI speed) I need about 12 iterations.
For Fsck/2 SPI speed only 2x _nop; should be inserted…
I have no generic solution for this problem. Use full-duplex with dummy bytes, or disable SPI after one received bit.
And RTFM!